Endgame-120
This is a new version of a endgame benchmark with 120 unique hidden samples. The runner can be found here, but dataset is closed.
Background: this benchmark is testing reasoning ability. Models need to solve a puzzle in a single turn. In a simul setup multiple puzzles need to be solved in one request. Here we do a pilot of the hidden dataset solving one puzzle per attempt to establish a baseline.
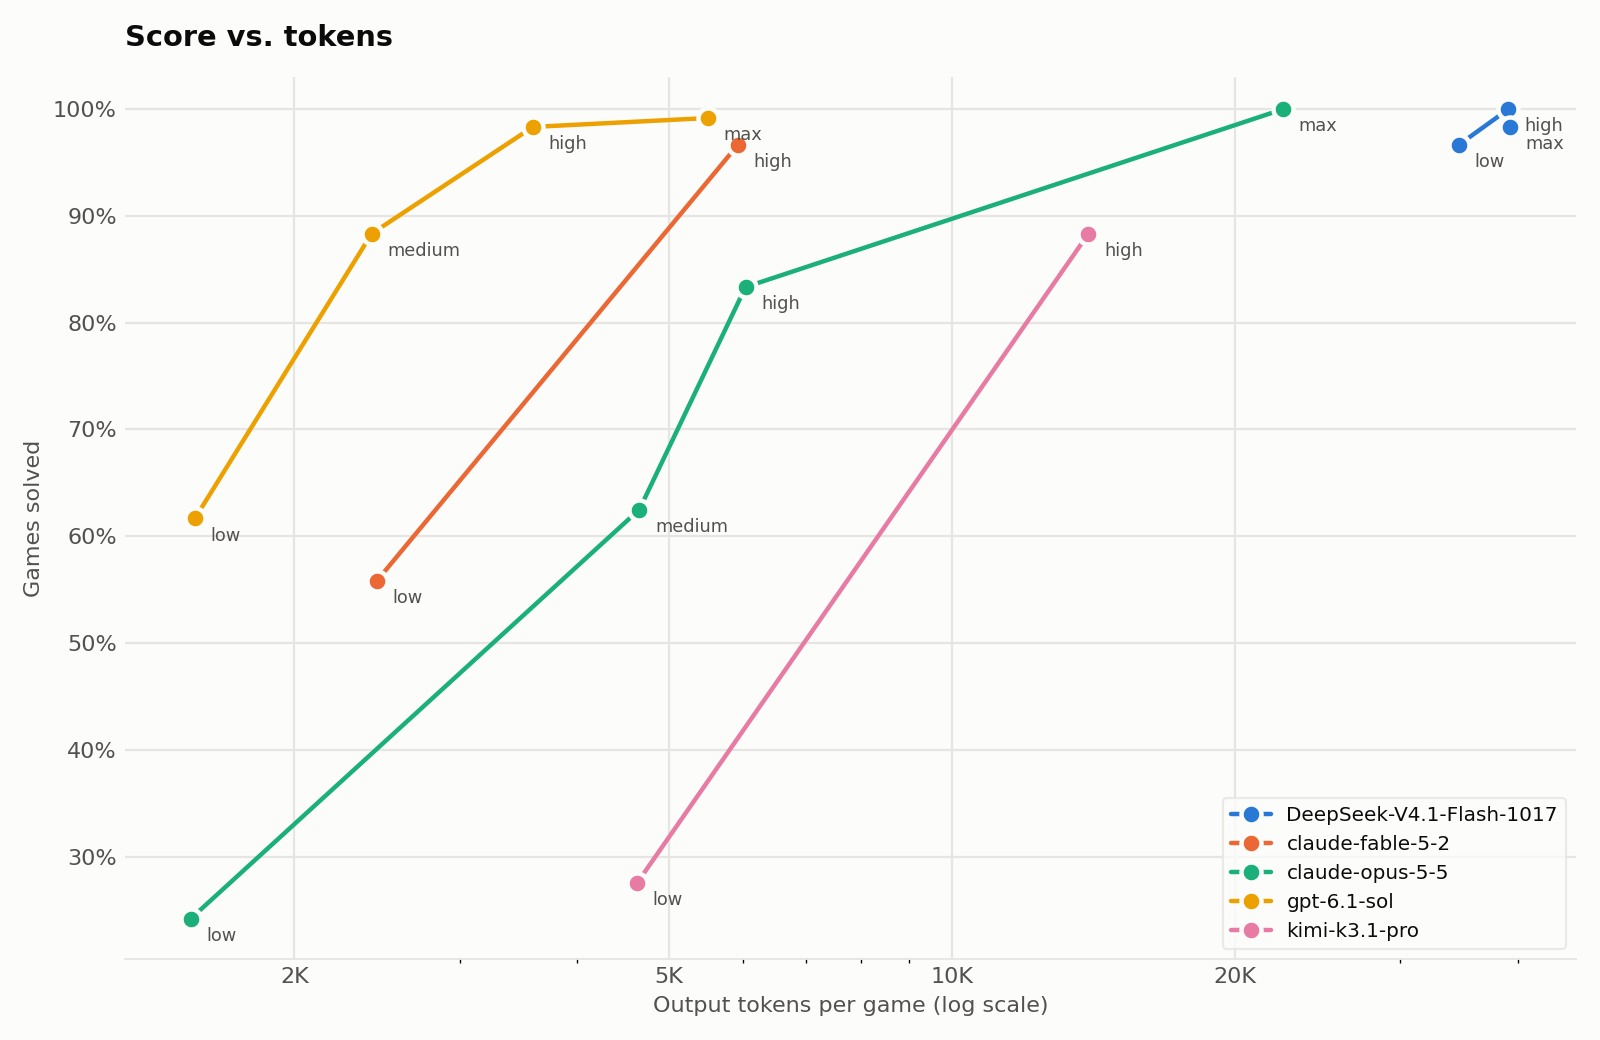
The cost dimension is preresented as tokens, not $, because providers can change pricing and tokens have hard limits: context window and max output, so it’s important to understand the cost in that currency.
On a very first glance, Sol-6.1 looks very good. Deepseek Flash is very capable, but requires lots of tokens even at low reasoning effort - there is, in fact, not that much difference between the predefined levels.
At max reasoning models are getting close to perfect score, so a harder version of the same benchamark with multiple puzzles is the next thing to test.